
Network monitoring and our own NOC
From our NOC we monitor our clients’ networks in real time and act remotely before your users notice.
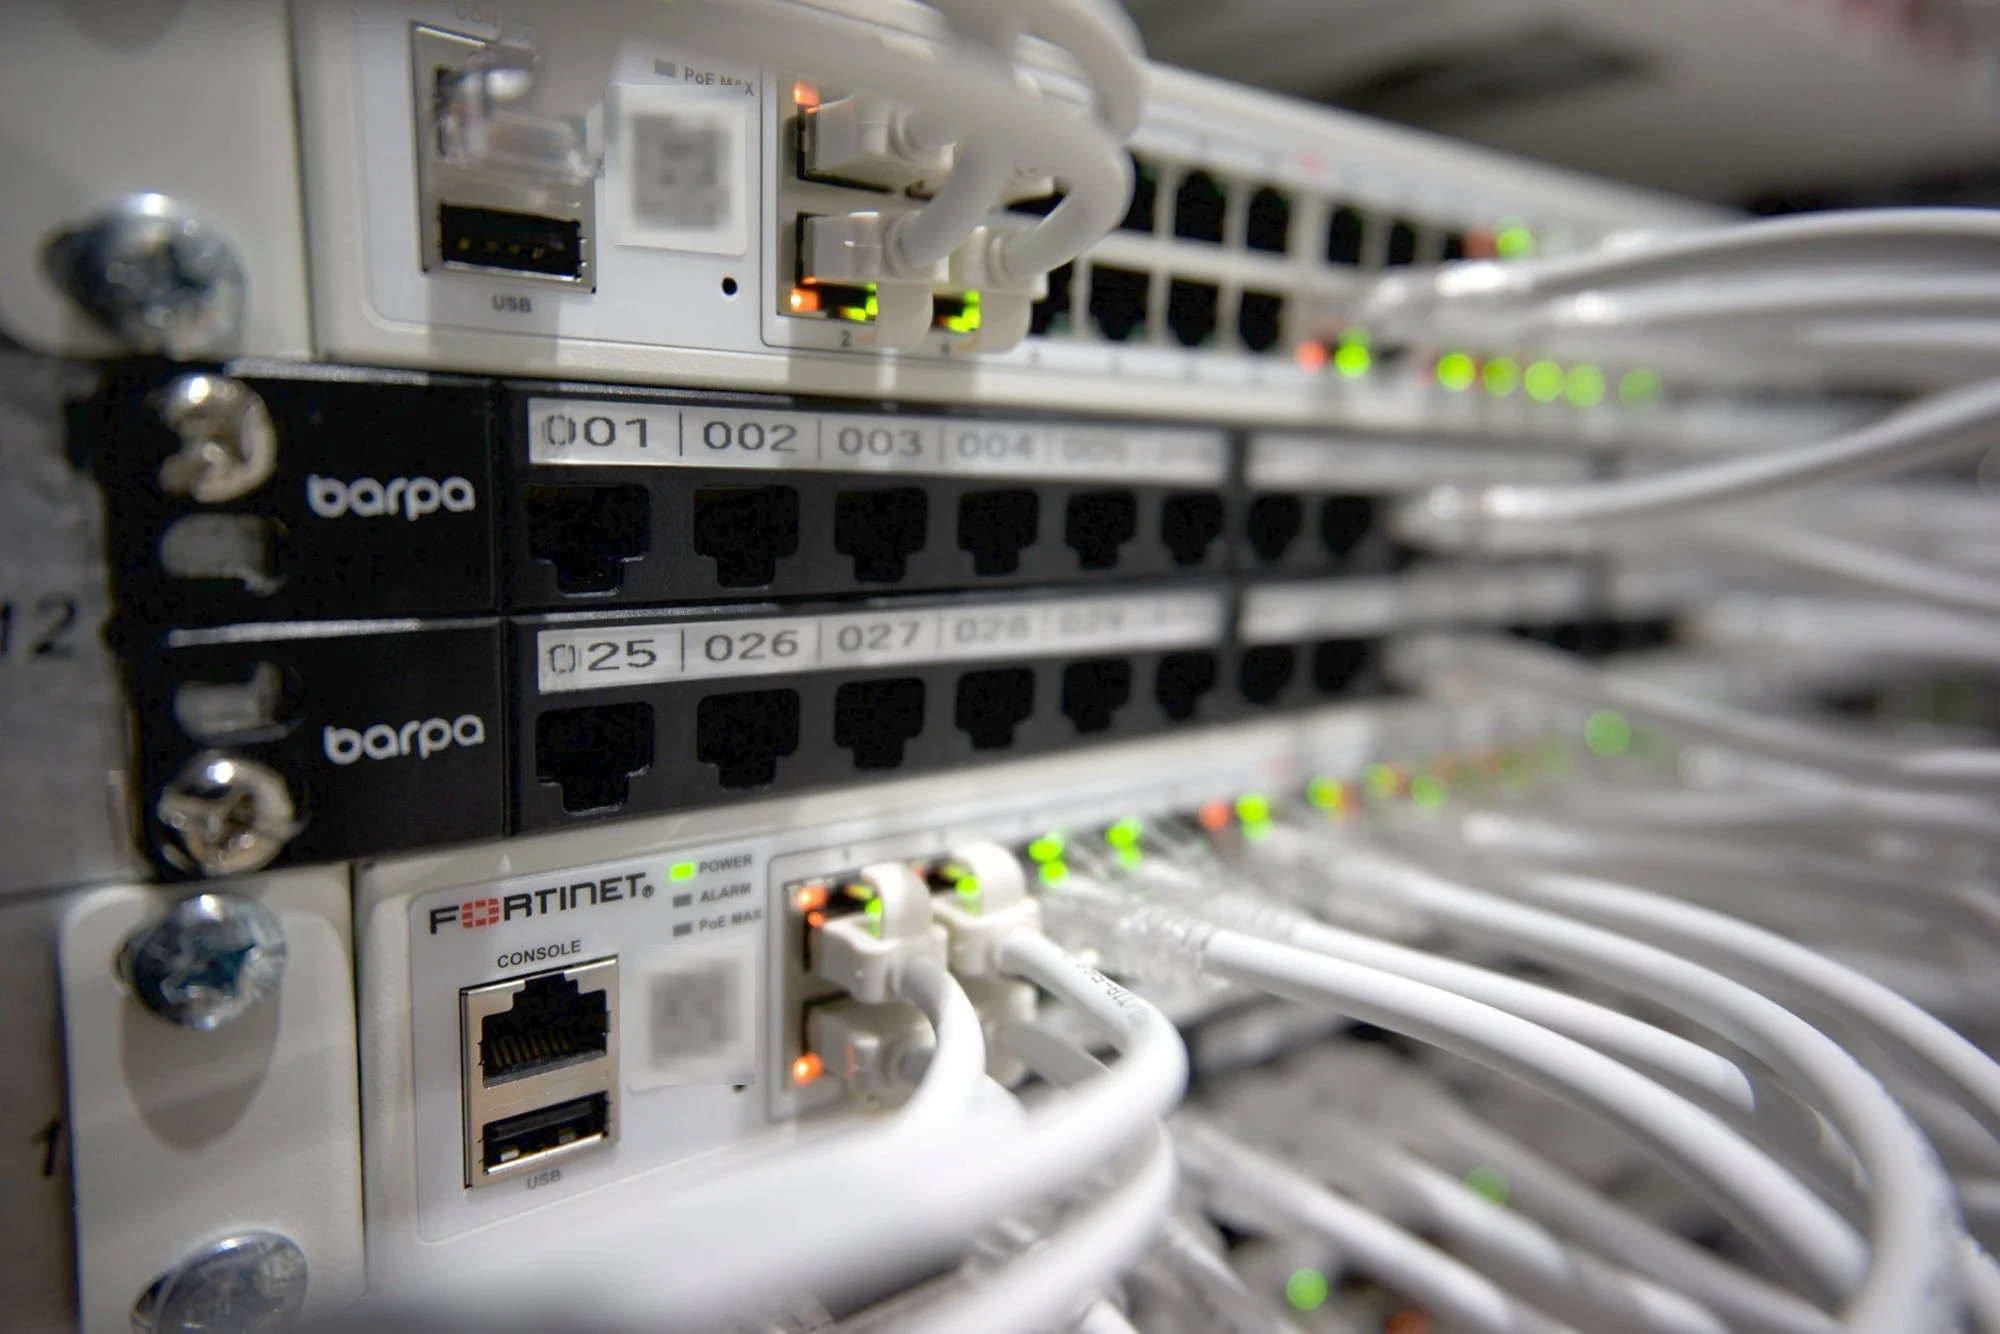
Our own NOC
Our own network operations centre
We run our own NOC (Network Operations Center), from which we centralise monitoring and management of our clients’ networks.
The central platform is LibreNMS: sites, switches, routers, firewalls, access points, servers, WAN links, VPNs and other critical devices, in real time and from a single environment. We keep performance history and raise automatic alerts on incidents or unusual behaviour.
What we measure
- Availability of devices, sites and links
- Traffic and bandwidth
- Latency and packet loss
- Interface status and errors
- CPU, memory and temperature
- PoE draw
- WAN links and VPN tunnels
What it brings
Detect, locate and resolve sooner
From the NOC, the Wired engineering team spots degradation, quickly finds the source of an incident and acts remotely. Less time to diagnose and to resolve.
Real time
Status and availability of every device and link, instantly.
History
Traffic, latency and usage stored to see trends and size things with data.
Automatic alerts
Alerts on incidents or unusual behaviour, before a user calls.
Remote action
We find the source and act remotely, without waiting for a site visit.
Multi-vendor
LibreNMS brings infrastructure from multiple vendors into one console:
Wired doesn’t just design and install the network: we monitor, run and maintain it throughout its lifecycle.
Incident management
From alert to resolution
Our NOC doesn’t just watch dashboards. When an incident is detected, the engineering team analyses it, identifies the affected element, assesses the impact and acts on the infrastructure.
- Detection
- Alert
- Diagnosis
- Action
- Verification
- Closure
When the fix depends on a carrier, vendor or third-party supplier, we follow up the incident technically until service is restored.
Centralised visibility
We integrate devices and services over SNMP, ICMP, Syslog and APIs, depending on what each platform supports, to correlate what happens on every element of the infrastructure.
- SNMP
- ICMP
- Syslog
- APIs
A single view of every site
Head office, other sites, warehouse, cloud services and remote working in the same NOC: we know which site, link or device is failing, and where it’s being felt.
Diagnosis
What happens when nobody watches the network
What we find
What we do
You find out about an outage when a user calls
Monitoring of devices and links, with alerts before anyone notices.
If the carrier goes down, everything stops
We monitor the main and backup links, and design the network so failover is automatic when there’s redundant connectivity.
Nobody knows if the backup works
Backups monitored, together with servers and storage.
Every network change is an adventure
Planned changes on a network we know and have documented.
The person who built the network has left
Up-to-date documentation and a team that knows your infrastructure.
What we do
The network isn’t finished the day it’s installed
After go-live we’re still there: monitoring, maintaining and evolving the infrastructure.
Monitoring and alerts
Network devices, firewall, Wi-Fi and links under watch, with alerts designed for your network.
Links and failover
Tracking of the main carrier and the backups. Automatic failover is handled by the firewall or SD-WAN we design for it.
Servers and backup
Servers, virtualisation, storage and backups.
Remote support
Diagnosis and changes carried out remotely and securely.
On-site engineers
When a visit is needed, it’s an engineer who knows your network.
Evolution
Expansions, changes and new sites on a network we already know.
In detail
How we work
Monitoring
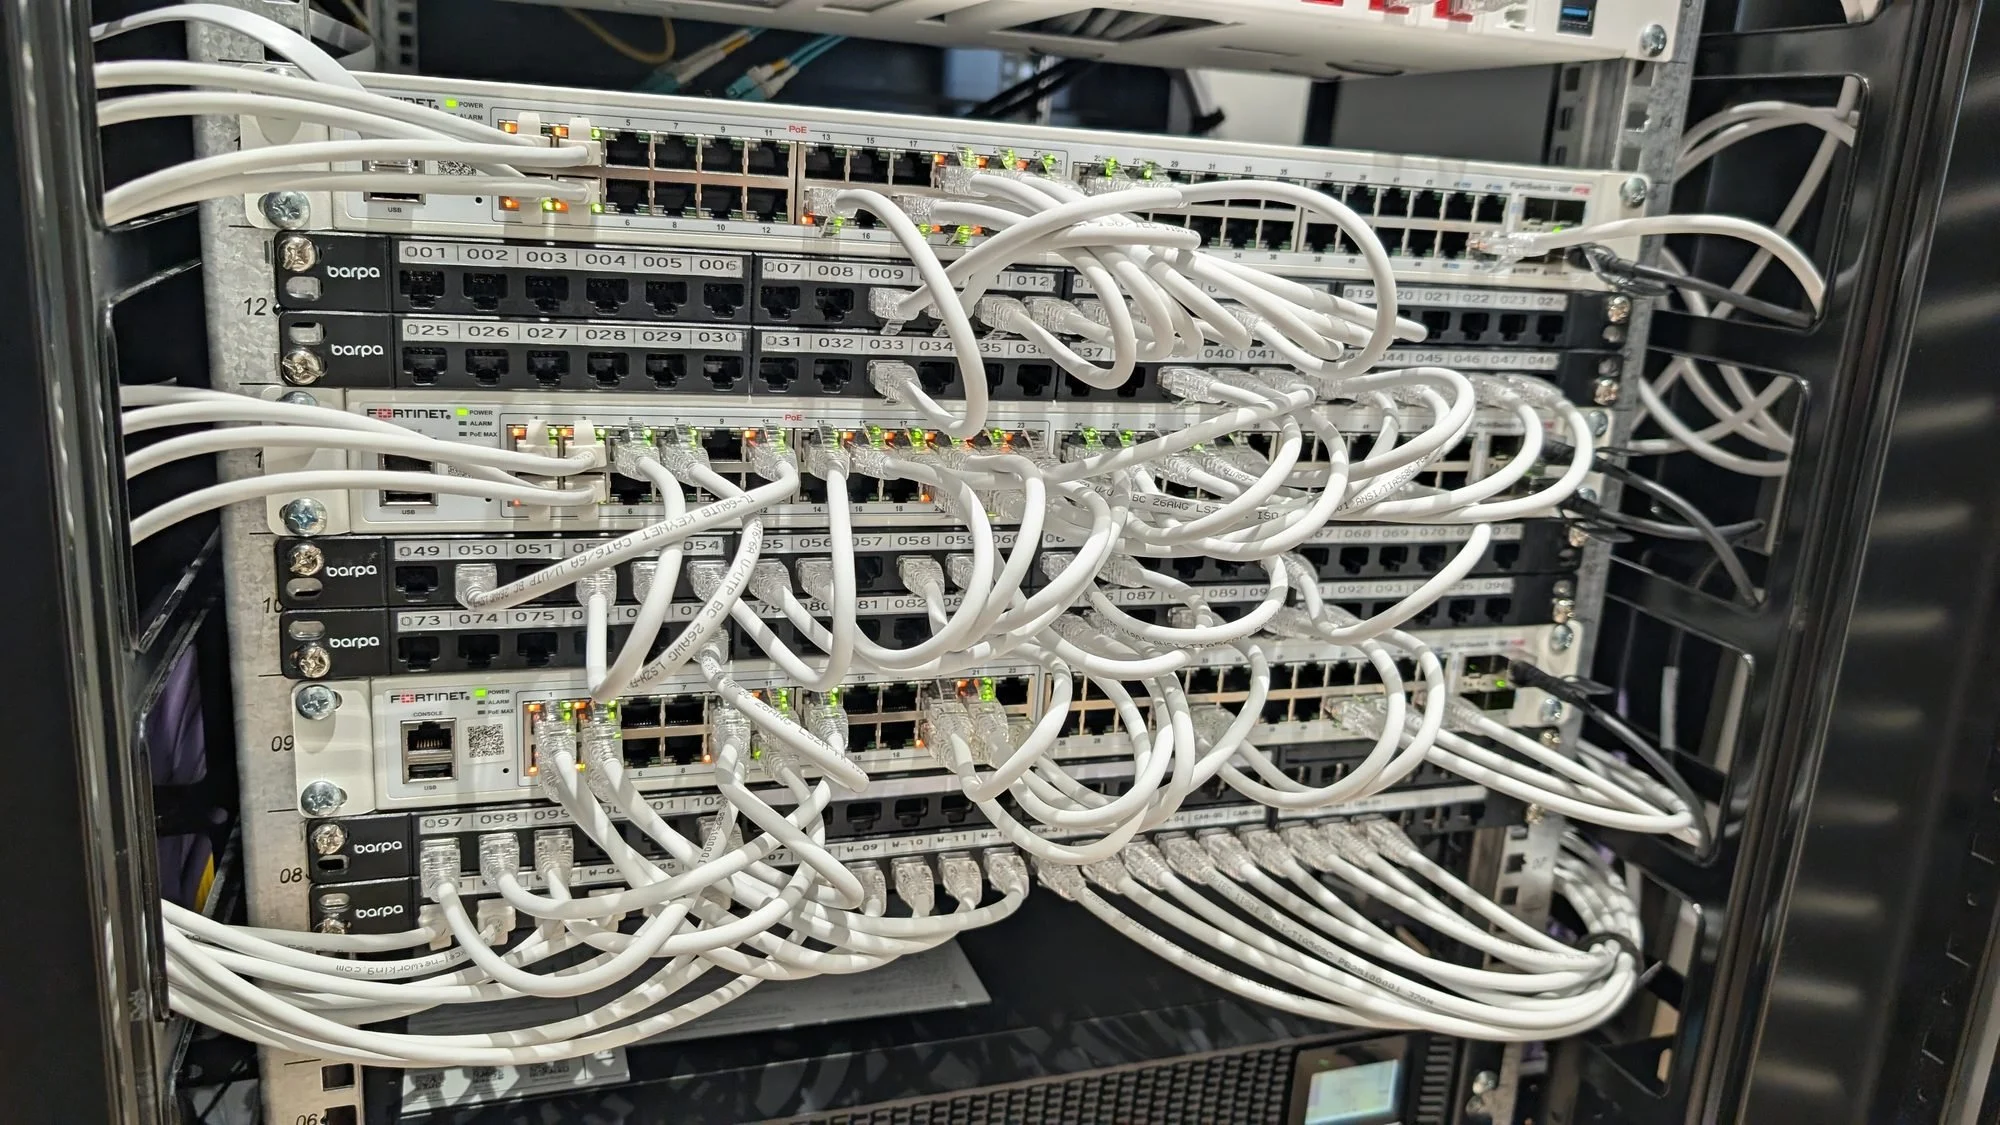
We watch what holds the network up
The network equipment, firewall, Wi-Fi and internet links. And, if you ask us to, servers, storage and backup too.
- Network devices and firewall
- Wi-Fi and internet links
- Servers and backup
Continuity
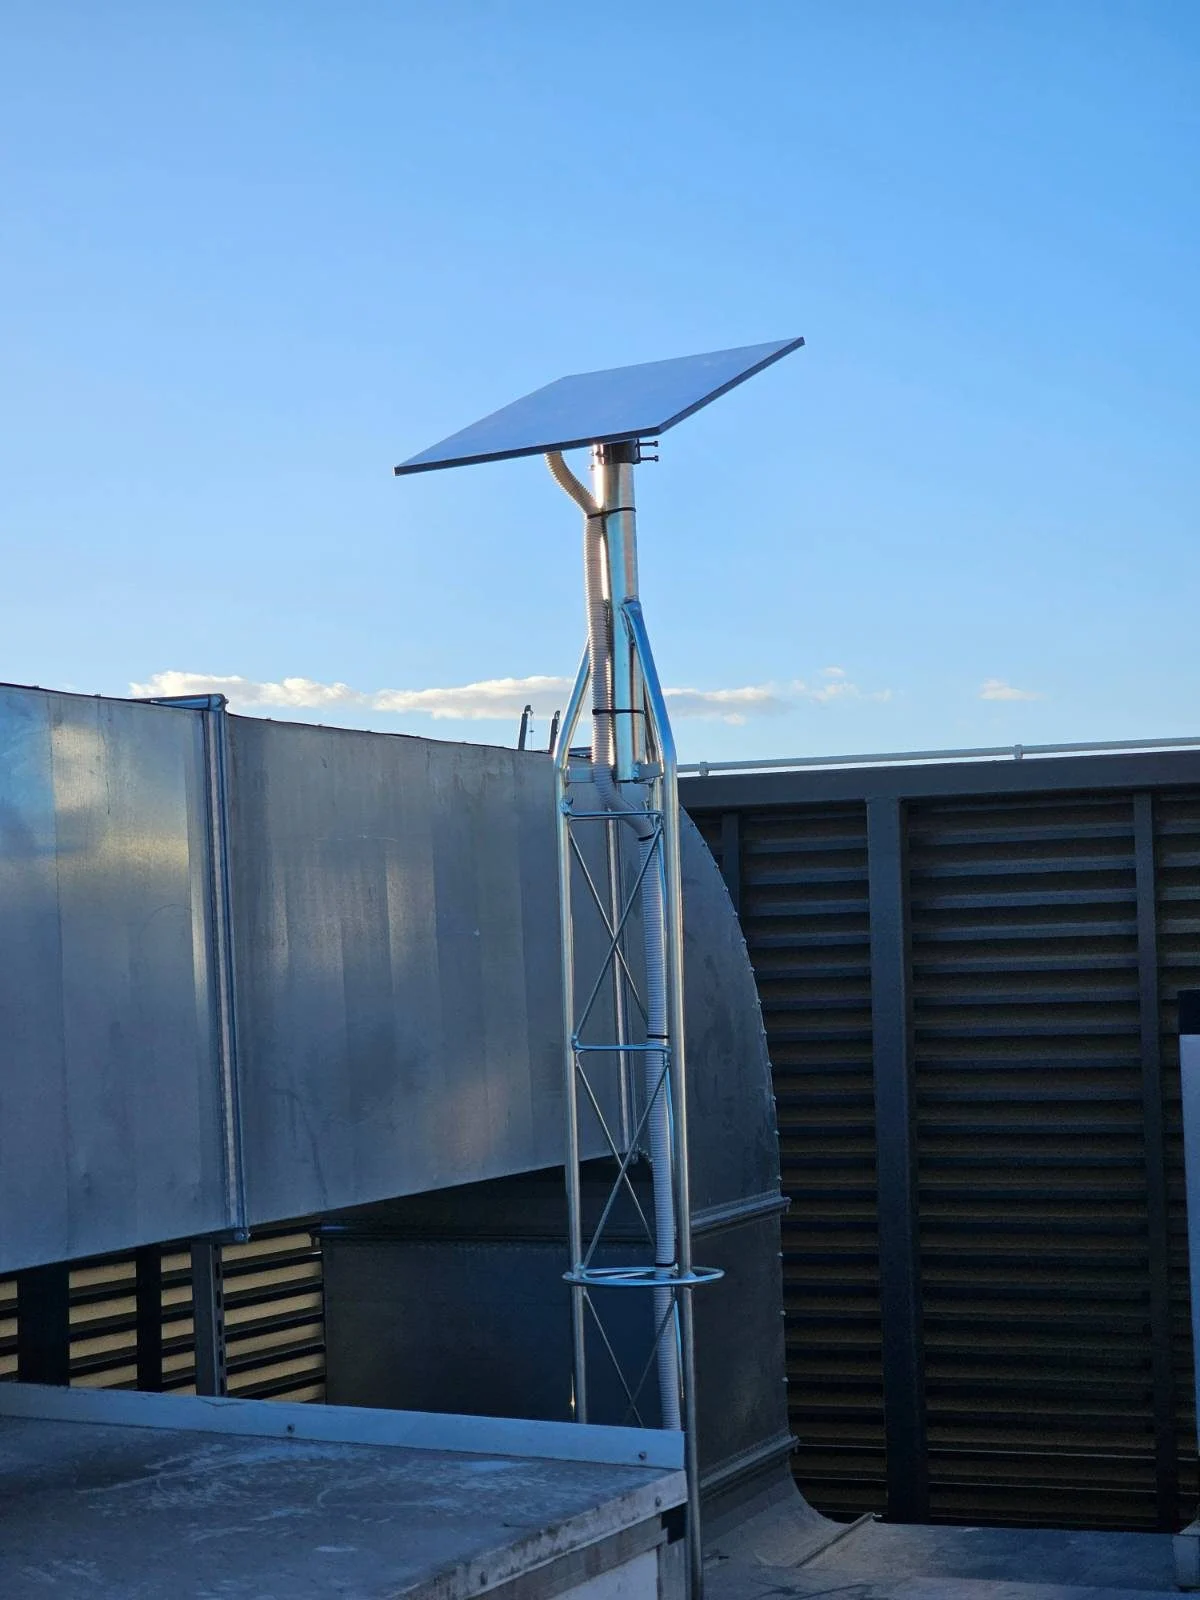
When the carrier fails
We track the status of the main link and the backups. If the carrier goes down, the firewall or SD-WAN switches traffic to the backup; we prove it with failover and failback tests.
- Link monitoring
- Tested failover and failback
- 5G or Starlink backup
Support
Remote or at your office
Whatever can be fixed remotely is fixed remotely, securely. When a visit is needed, it’s an engineer who knows your network.
Case study
En Directe Plurals: the infrastructure we built, we still run
Live subtitling for broadcasters: a high-availability network, fibre to the CCMA and QoS for video. Since we installed it, we’ve run and maintained their infrastructure.
Fibre links with the CCMA
2
Video traffic
Prioritised with QoS
Centralised UPS
10 kW
Operations
Ongoing
Projects
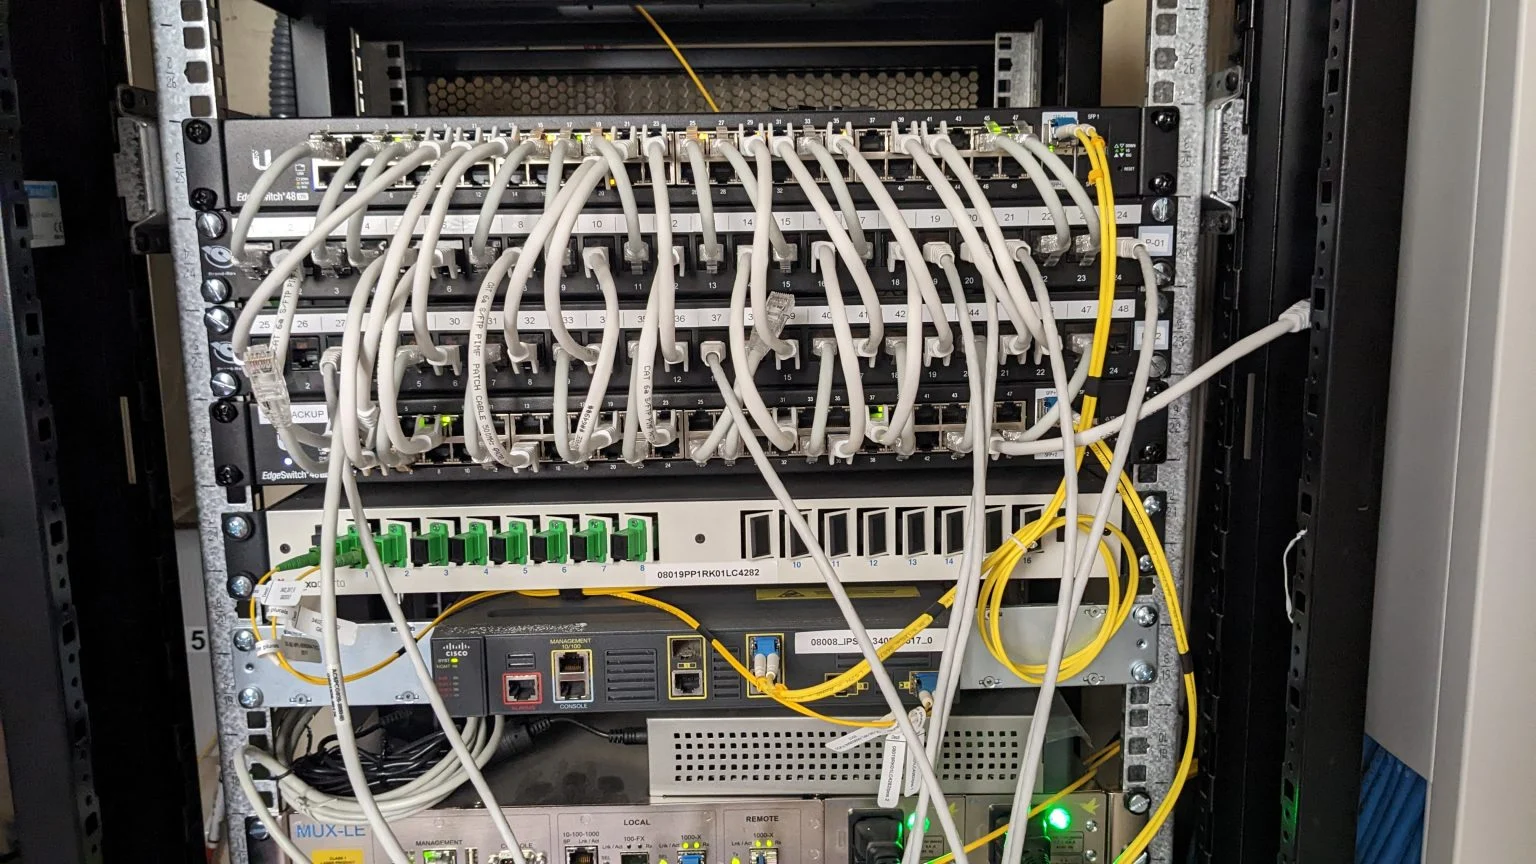
Infrastructure we still run
FAQ
What monitoring tool do you use?
LibreNMS, from our own NOC. It’s a multi-vendor platform: it brings Cisco, HPE Aruba Networking, Fortinet, RUCKUS, Ubiquiti, Juniper and other vendors’ equipment into a single console.
What do you monitor?
Network equipment, firewall, Wi-Fi, internet links and, if you ask us to, servers, storage and backup.
Do you come to the office?
Yes. We fix remotely whatever we can and send engineers when needed.
Do you also look after servers and backup?
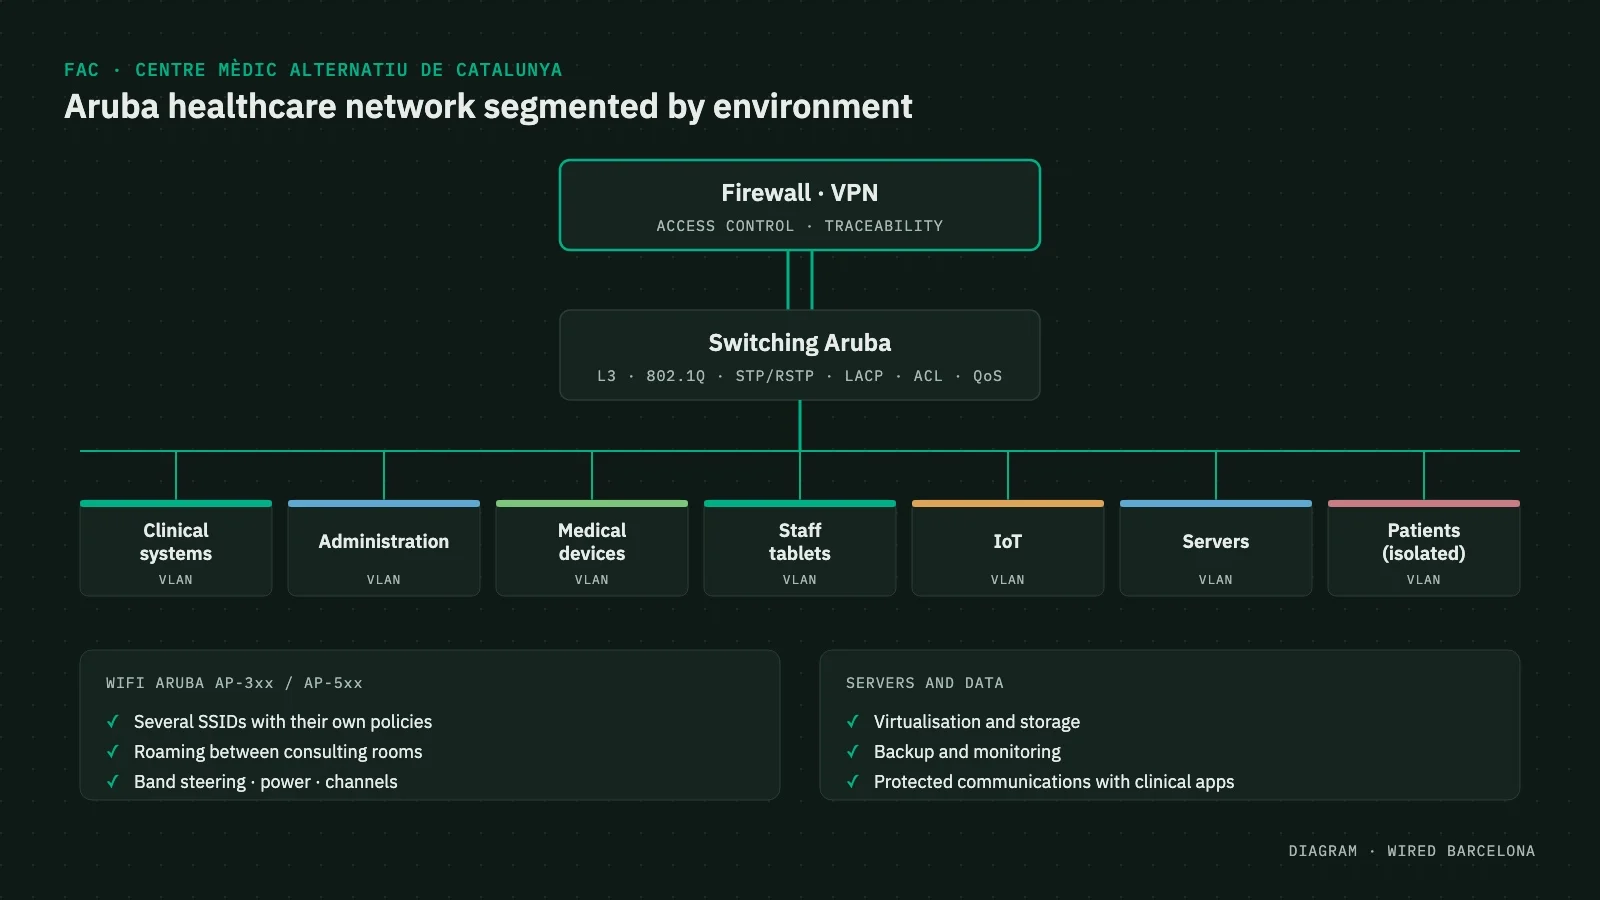
Yes: servers, storage, virtualisation and backup, as at FAC.
Self-assessment
Would you hear about an outage before your users?
Monitoring, alerts, SLA and service continuity: the self-assessment tells you in three minutes where your network operations stand.
Related services